How soma works
soma takes a cohort of images with labels and splits, extracts features with a frozen foundation model, trains a downstream model on those features, and scores its predictions. Inputs can be tiles, regions of interest or whole slides, and the same steps serve classification, regression, survival, segmentation and detection.
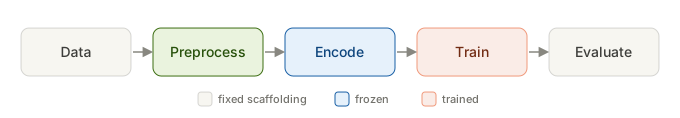
A frozen foundation model produces reusable features. The downstream model is trained for the task.
The steps
Each step is a public function, a verb, that takes and returns plain objects you can inspect:
Step |
Verb |
What you choose |
Learn more |
|---|---|---|---|
Data |
|
Images, targets, and train/tune/test or K-fold splits |
|
Preprocess |
|
Tissue masking, spacing, tile size and overlap |
|
Encode |
|
A frozen foundation model; its features are cached for later runs |
|
Train |
|
An aggregator or a decoder, a task head, the optimizer and the budget |
|
Evaluate |
|
Metrics and subgroups |
Features reach the downstream model in one of two shapes. A set is one feature
vector per sample, or a bag of tile features that an aggregator pools; the mil
learner trains it, with a classification, regression or survival head. A grid is
a dense token grid per tile or region that a decoder maps back to pixels; the
dense learner trains it, with a segmentation or detection head. Modeling
helps you choose.
Three ways to run
A preset returns a complete experiment for a common task from a few arguments, such as
soma.presets.mil_classification(encoder="uni2"), orsoma run --preseton the command line.A config, an
soma.ExperimentConfigin Python or the same fields in YAML, states every step.soma.resolve()expands it into asoma.Planwith every default filled in, andsoma.Pipelineruns it: extraction, every fold, and the run directory.The verbs, called one by one.
Pipelinecalls the same verbs in a fixed order, so a run composed by hand gives the same predictions and weights, and you can change any step and hand the result back to the pipeline.
The getting-started notebook takes one experiment through
all three. Every managed run writes a run directory: the config as given
(config.yaml), its plan (plan.yaml), the predictions, the metrics, and one
model bundle per fold (see Run outputs).
Compare experiments
Features are cached under the image, preprocessing and encoder settings, so runs that change only the downstream model reuse them; Caching explains when extraction must run again. For a controlled comparison, hold the cohort, labels, splits and the rest of the protocol fixed while varying one component. Registered benchmarks are fixed protocols for reproducing public results and comparing encoders.
Use cases
Each use case is a preset (or a task head swapped into one) over one source shape. The end-to-end scenarios in the last column run it in soma’s test suite, on synthetic images with a weight-free encoder; tests/e2e/README.md lists what each scenario checks.
Use case |
Preset or head |
Source |
End-to-end scenario |
|---|---|---|---|
Slide classification |
|
Bags of tile features |
|
Survival |
|
Bags of tile features |
|
Regression |
The |
Bags of tile features |
|
Tile-level classification |
|
One embedding per image |
|
Segmentation |
|
Dense token grids |
|
Detection |
|
Dense token grids |
|
Next: install soma, then run the getting-started notebook.